Checkpoints & progress
Progress logic is identical for drone-racing gates and car-racing tracks: discrete pass events plus a distance-to-next-goal signal. The utilities split it into a shared goal contract and a stateful tracker.
Checkpoints: one contract, two sources
track_gen.checkpoints.CheckpointSet is an ordered list of course goals
per env — center position, a physical crossing segment left <->
right, and a forward tangent:
from track_gen.checkpoints import CheckpointSampler, CheckpointSet

cps = CheckpointSet.from_gates(gate_seq)          # zero-copy gate view
cps = CheckpointSampler(track, spacing=0.6).sample()   # virtual gates
from_gates aliases the GateSequence buffers (regenerated gates are
seen automatically). CheckpointSampler subsamples the CENTERLINE at a
coarse spacing; because track polylines are index-aligned, each checkpoint’s
crossing segment is the road cross-section between inner and outer.
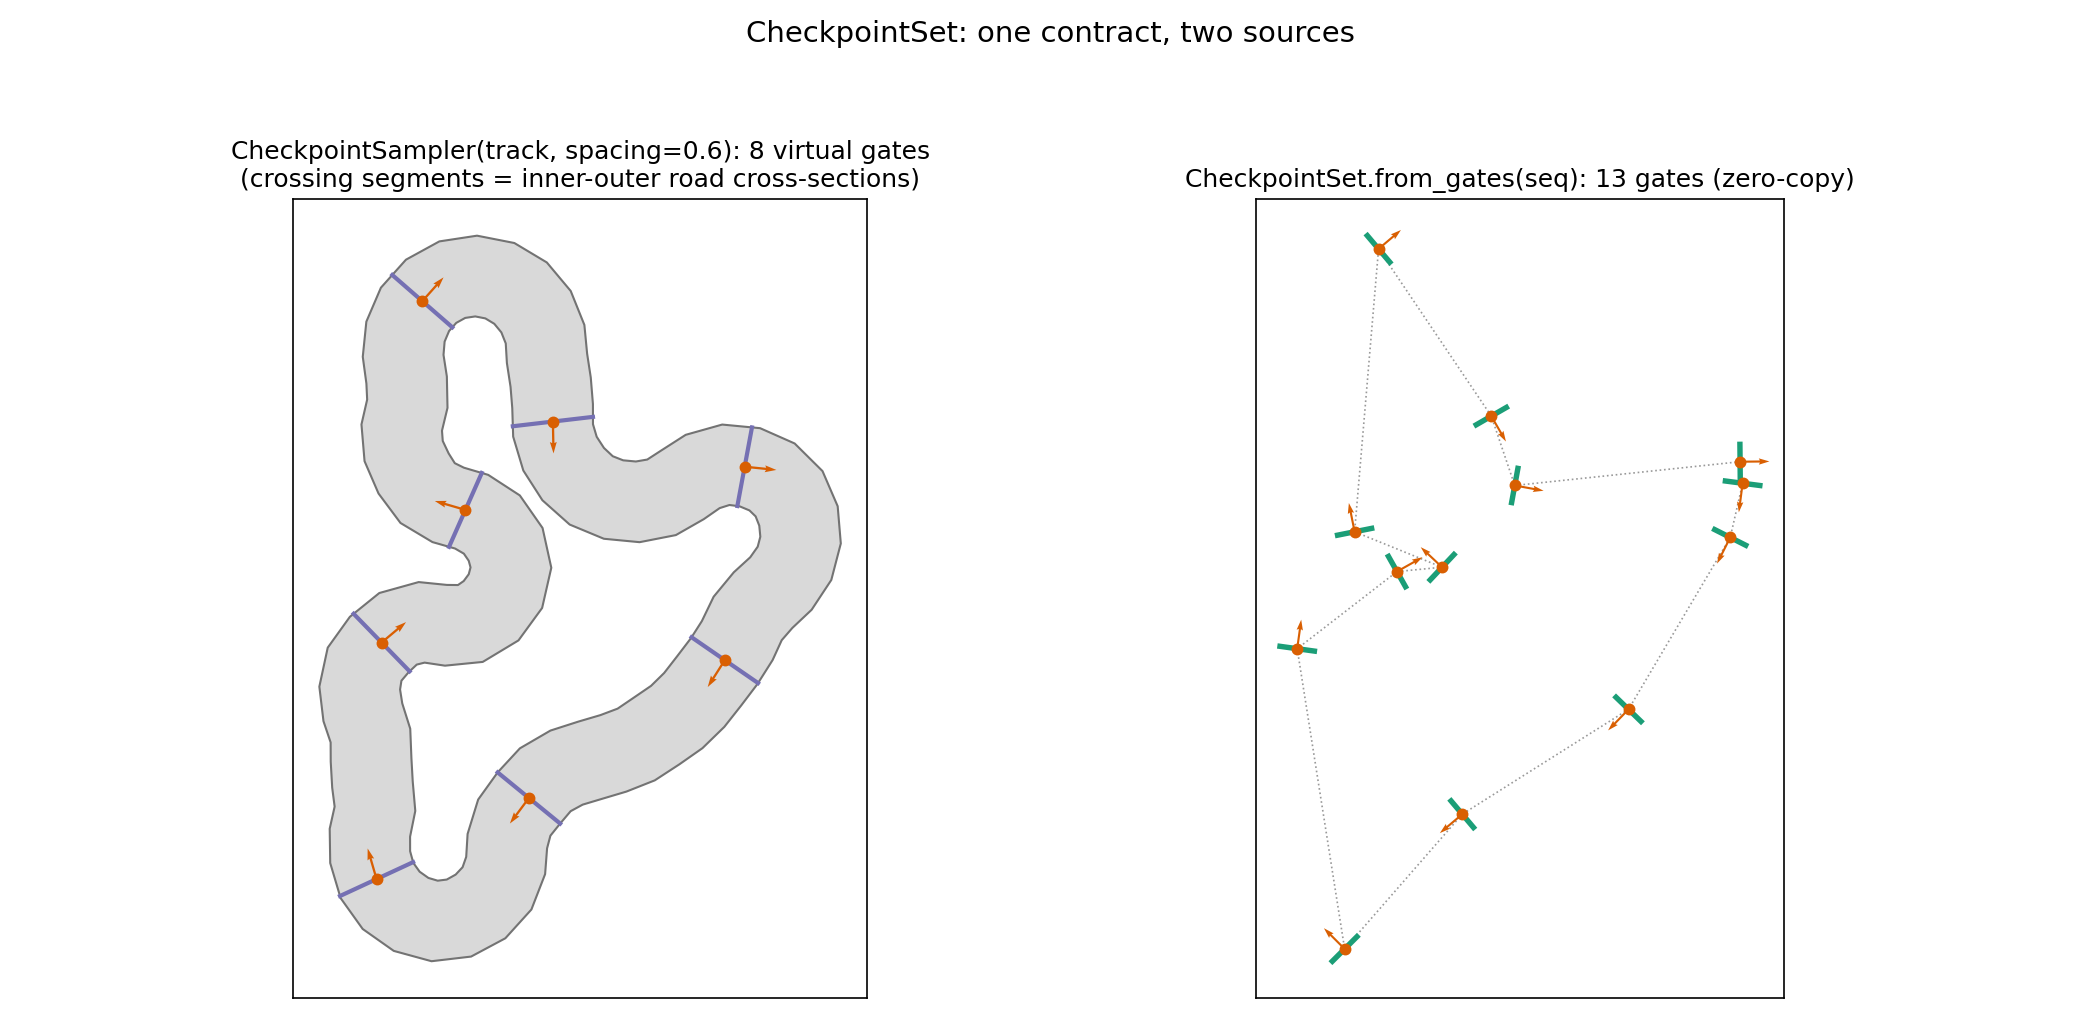
The same CheckpointSet contract from a subsampled track (left) and a
gate sequence (right).
Progress tracking & rewards
track_gen.progress.ProgressTracker consumes any CheckpointSet and
maintains per-env device state: previous position, next target, laps, total
progress. Each update() detects forward pass-through of the target’s
crossing segment (swept-segment test), wrong-way and wrong-checkpoint
crossings, and reports dist_to_next — the distance to the next goal:
from track_gen.progress import ProgressTracker

tracker = ProgressTracker(cps, position=robot_pos)  # latch onto sim buffer
prev_d = None
for _ in range(steps):
    sim.step()                       # writes robot_pos in place
    ev = tracker.update()            # no args: bound mode
    d = wp.to_torch(ev.dist_to_next)
    reward = (prev_d - d) if prev_d is not None else 0.0   # -delta distance
    reward = reward + 10.0 * wp.to_torch(ev.passed)        # pass bonus
    prev_d = d.clone()
tracker.reset(done_mask)             # episodic resets, per env
# `prev_d` above still holds the FINISHED episode's distance for envs
# reset this step; mask it (e.g. zero the reward) before differencing.
reset(mask) arms a NaN previous-position sentinel, so the first step
after a reset (or a teleport respawn) can never emit a spurious crossing.
After regenerating the course (gates or track), call reset for all envs.
That sentinel protects the TRACKER’s own crossing/wrong-way detection only —
the caller-side -delta distance reward term needs its own masking, since
prev_d for a just-reset env is stale (from the episode that just ended)
and differencing it against the freshly reset dist_to_next is not a
meaningful reward.
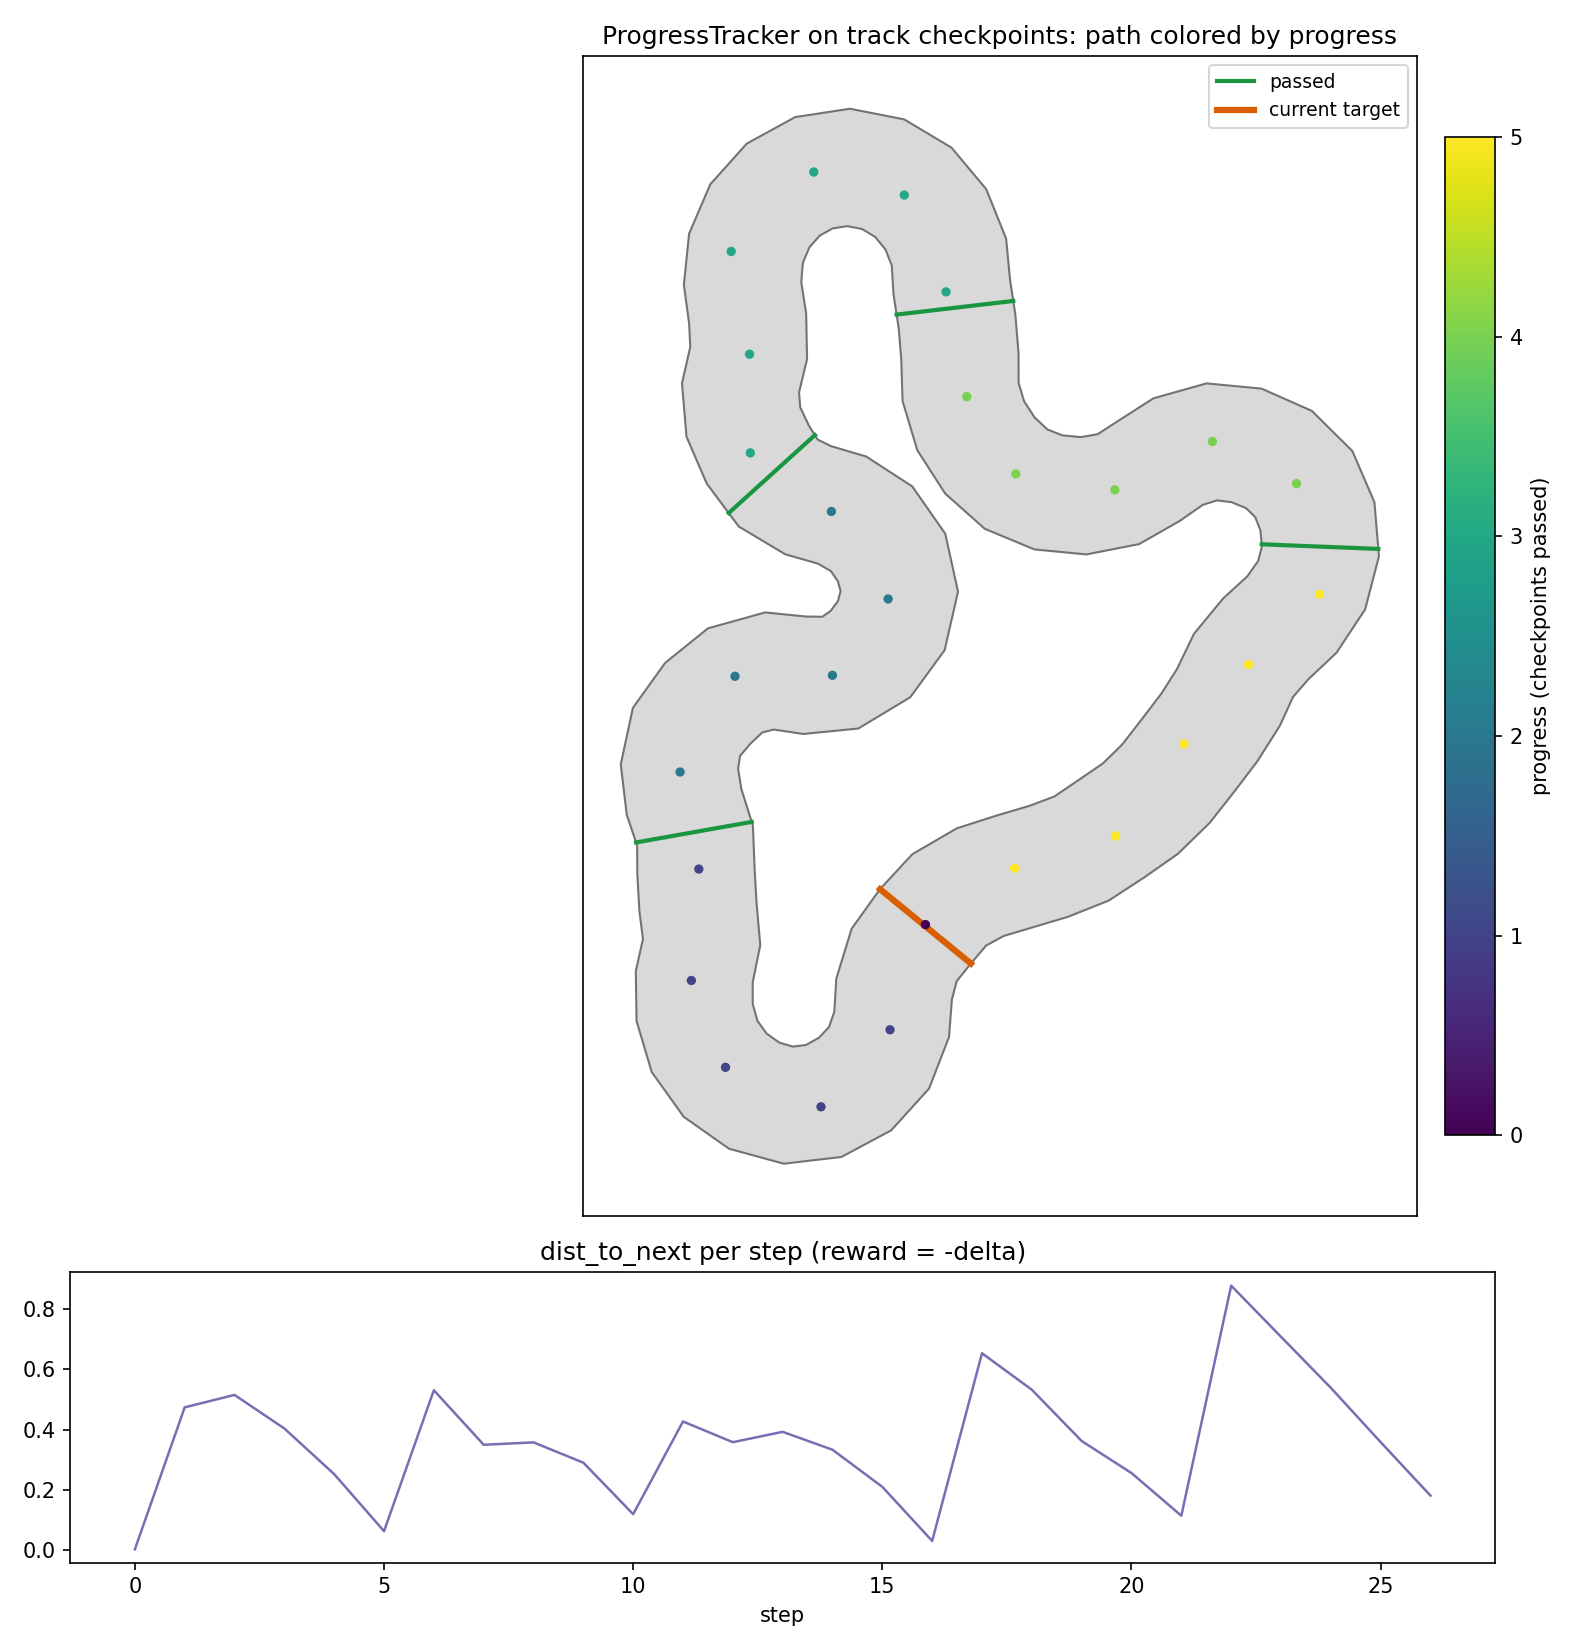
A scripted agent threading track checkpoints; the lower panel shows the
dist_to_next sawtooth your negative-delta reward differentiates.
API: track_gen.checkpoints.CheckpointSet,
track_gen.checkpoints.CheckpointSampler,
track_gen.progress.ProgressTracker — see the
API reference.